FTerViT: Fully Ternary Vision Transformer for Microcontrollers
Pietro BonazziETH Zurich | CSEM
The Problem
Ternary Vision Transformers offer substantial model compression, but state-of-the-art methods only ternarize the encoder layers, leaving patch embeddings, LayerNorm parameters, and classifier heads in full precision. In compact models targeting microcontrollers, these remaining full-precision components dominate the memory footprint.
Our Approach
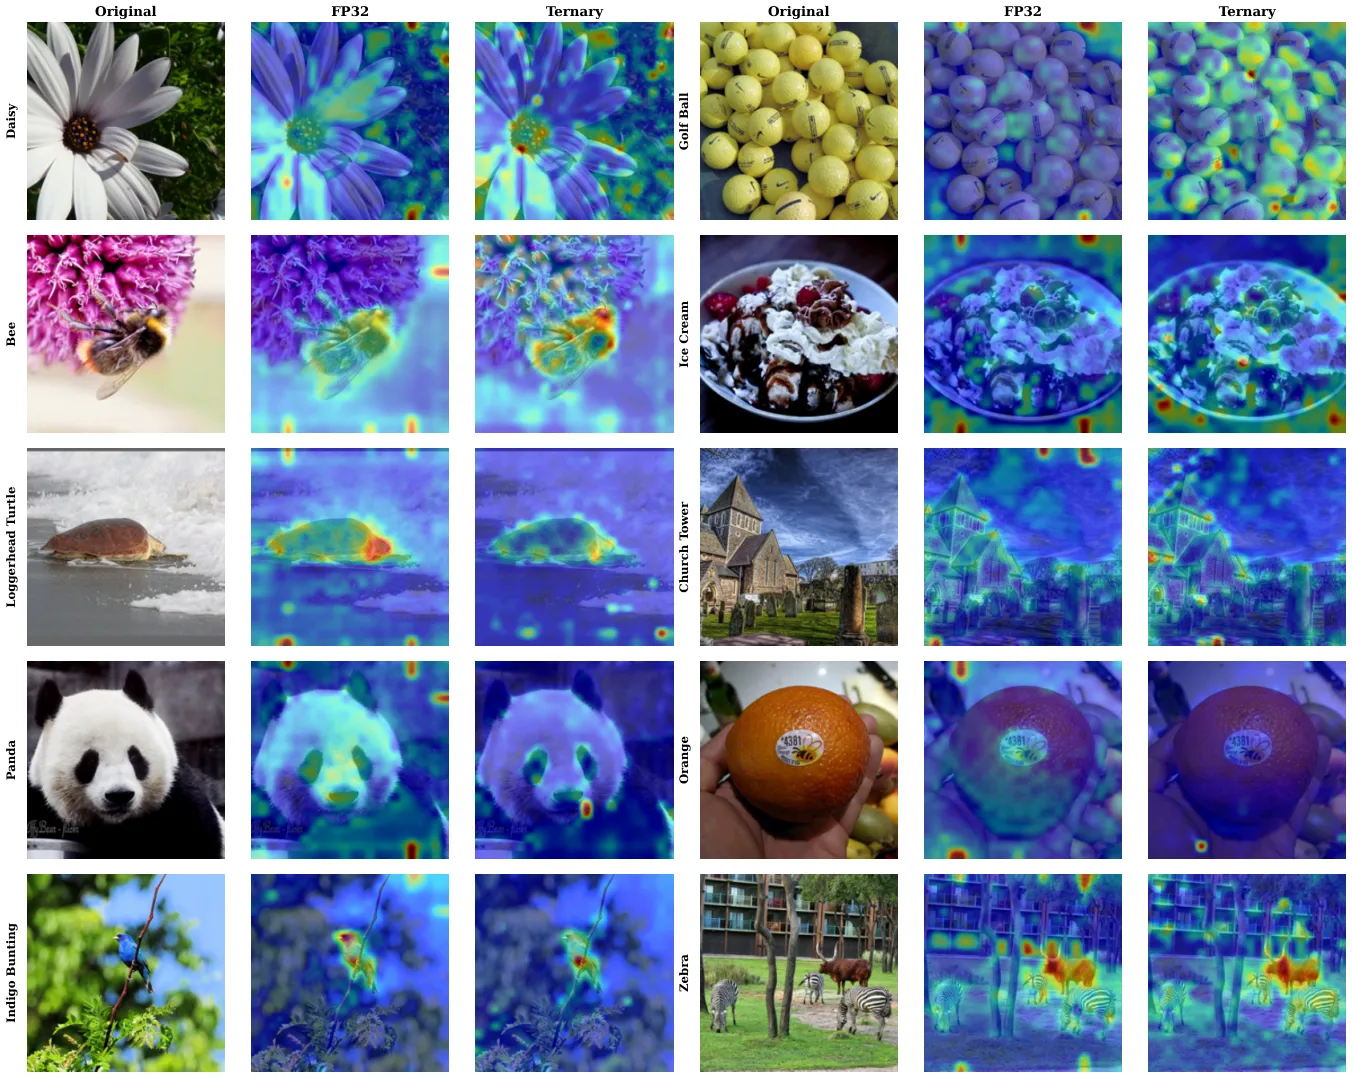
We introduce FTerViT, the first fully ternarized Vision Transformer in which all weight matrices and normalization parameters are ternarized. Two novel operators enable this:
- TernaryBitConv2d -Per-channel scaling for patch embedding ternarization
- TernaryLayerNorm -Replaces standard LayerNorm with ternary-compatible normalization
The model is trained using knowledge distillation, followed by a lightweight quantization-aware recovery phase.
Results
- 82.43% top-1 on ImageNet-1K with W2A8 DeiT-III-S at 384x384 (6.09 MB, ~15x compression)
- Outperforms prior ternary ViT methods by up to 8 pp
- First ternary ViT deployed on a microcontroller -ESP32-S3 (dual-core XTensa LX7), achieving 79.64% ImageNet-1K top-1 at 5.81 MB